Every minute your website stays down costs more than just lost clicks – it hits your bottom line hard. Relying on a single data center is a risk few can afford when revenue depends on uptime. That’s why active active geo redundancy hosting with multi data center automatic failover has become the backbone of 99.99 uptime enterprise hosting. Let’s break down the website disaster recovery strategy that keeps your site live no matter what.
Understanding the True Cost of Downtime
Revenue loss begins the moment your website goes offline. For e-commerce operations, every second of unavailability translates directly to abandoned carts, frustrated customers, and competitors gaining market share. Studies show that a single hour of downtime can cost enterprises anywhere from $100,000 to over $5 million, depending on industry and scale.
Beyond immediate revenue impact, downtime damages brand reputation in ways that extend far beyond the incident itself. Customers who encounter unavailable services often choose not to return, even after systems are restored. Search engines penalize sites with poor availability, affecting organic rankings and long-term visibility. Payment processors may increase fees or impose restrictions on merchants with unreliable infrastructure.
The financial implications compound when you factor in productivity losses, emergency response costs, and potential regulatory penalties for industries with strict availability requirements. This reality makes investing in a comprehensive website disaster recovery strategy not just prudent but essential for business continuity.
The Single Point of Failure Problem
Traditional hosting architectures create vulnerabilities that can bring entire operations to a halt. When your infrastructure relies on a single data center, you face exposure to numerous catastrophic scenarios. Natural disasters, power grid failures, network outages, hardware malfunctions, and even human error can render your services completely inaccessible.
Many organizations believe their backup systems provide adequate protection. They maintain secondary servers in the same facility or region, assuming this redundancy offers sufficient safety. This approach fails to address the fundamental issue: when the primary data center experiences problems, all systems within that location become compromised simultaneously.
Geographic concentration of resources creates risk concentration. A regional power outage affects both primary and backup systems. A natural disaster impacts all infrastructure in the affected area. Network issues at the facility level cascade across supposedly independent systems. The illusion of redundancy collapses precisely when you need it most.
Active Active Geo Redundancy Hosting: The Foundation
Active active geo redundancy hosting represents a fundamental shift in how we approach availability. Unlike traditional active-passive configurations where backup systems remain idle until needed, active-active architectures distribute live traffic across multiple geographically dispersed data centers simultaneously.
This approach means every data center in your infrastructure actively serves customer requests at all times. Traffic routes to the nearest or best-performing location based on intelligent routing protocols. If one region experiences issues, the others continue operating without interruption. Users experience no service degradation because capacity already exists across all locations.
The architecture requires careful synchronization of data and application state across regions. Database replication must occur in real-time or near-real-time to ensure consistency. Session management needs to work across geographic boundaries so users maintain their experience regardless of which data center serves their requests. Load balancing must intelligently route traffic based on health checks, latency, and capacity.
Implementing active active geo redundancy hosting requires expertise in distributed systems, network architecture, and database replication strategies. The complexity increases with the number of regions and the nature of your applications. Stateful applications present particular challenges that require sophisticated session management and data synchronization approaches.
Multi Data Center Automatic Failover Mechanisms
Multi data center automatic failover represents the operational component that makes geo-redundancy practical. Automation removes human reaction time from the equation, detecting failures and redirecting traffic within seconds rather than minutes or hours.
Health monitoring forms the foundation of effective failover. Systems continuously check application availability, database connectivity, network performance, and resource utilization across all data centers. These checks occur at multiple levels, from basic ping tests to sophisticated application-level validations that confirm actual functionality.
When monitoring detects degradation or failure, automated decision-making processes evaluate the situation and execute predetermined responses. DNS-based failover can redirect traffic at the domain level, pointing users to healthy regions. Load balancer-based failover operates at the network layer, immediately routing new connections away from troubled infrastructure. Application-level failover can handle granular scenarios where specific services fail while others remain operational.
The speed of failover directly impacts user experience. Modern multi data center automatic failover systems can redirect traffic in under 30 seconds, often much faster. This rapid response means most users never notice an issue occurred. Their requests simply route to a healthy data center without interruption or error messages.
Configuration of failover thresholds requires balancing sensitivity against stability. Too aggressive, and minor transient issues trigger unnecessary failovers that can actually reduce overall stability. Too conservative, and real problems persist longer than necessary before triggering remediation. Experienced teams tune these parameters based on application characteristics and business requirements.
Achieving 99.99 Uptime Enterprise Hosting
The goal of 99.99 uptime enterprise hosting translates to less than 53 minutes of downtime per year. Reaching this target requires eliminating single points of failure at every layer of your infrastructure stack.
Network redundancy means multiple internet service providers, diverse fiber paths, and redundant networking equipment. Any single network component can fail without affecting overall connectivity. Geographic distribution ensures regional network issues cannot impact global availability.
Compute redundancy spreads application servers across multiple data centers with sufficient capacity in each location to handle full traffic loads if other regions become unavailable. Auto-scaling capabilities allow rapid capacity expansion during traffic spikes or when regions go offline.
Storage redundancy replicates data across regions with consistent synchronization. Database architectures must support multi-master configurations or sophisticated primary-replica setups with automatic promotion. File storage, object storage, and caching layers all require geographic distribution with automatic failover capabilities.
Application architecture must support distributed deployment. Monolithic applications that cannot scale horizontally or operate across regions create barriers to achieving true high availability. Modern microservices architectures, containerized deployments, and cloud-native designs enable the flexibility required for 99.99 uptime enterprise hosting.
Monitoring and alerting systems must themselves be highly available. If your monitoring infrastructure fails, you lose visibility into your production systems. Distributed monitoring with redundant alert paths ensures operations teams receive notifications regardless of infrastructure state.
Building a Comprehensive Website Disaster Recovery Strategy
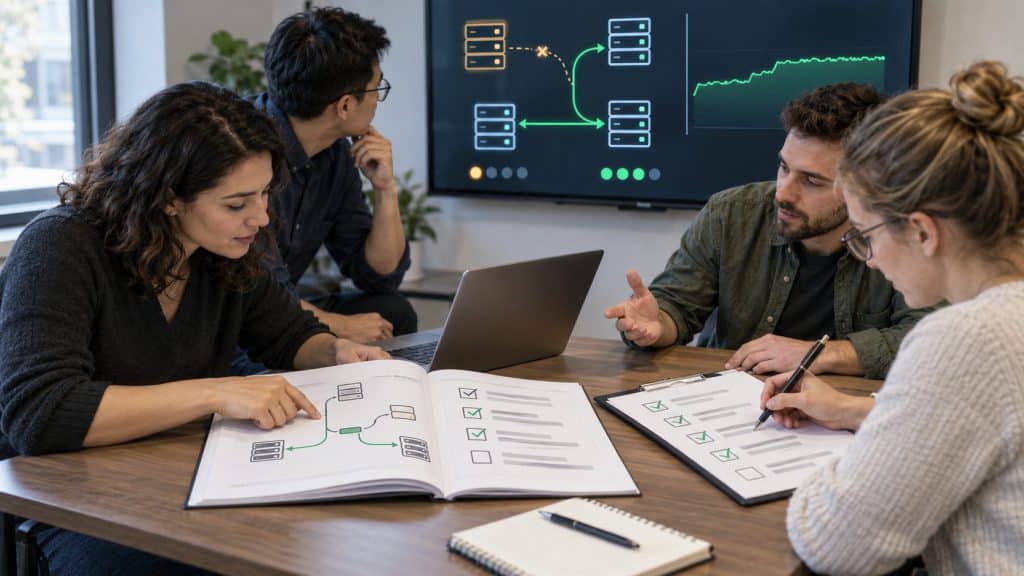
A complete website disaster recovery strategy extends beyond technology to encompass processes, documentation, and regular testing. Technology provides capabilities, but operational excellence determines whether those capabilities translate to actual resilience.
Documentation must cover architecture diagrams, failover procedures, recovery time objectives, recovery point objectives, and contact information for all relevant parties. This documentation needs regular updates as infrastructure evolves. Outdated documentation creates confusion during actual incidents when clarity matters most.
Runbooks provide step-by-step procedures for common scenarios. While automation handles most situations, edge cases and complex failures may require human intervention. Clear runbooks reduce response time and prevent mistakes during high-pressure situations.
Testing validates that your website disaster recovery strategy works as designed. Regular failover drills confirm that automated systems function correctly and that manual procedures remain current. These tests should occur during business hours when full teams are available, not just during maintenance windows. The goal is to build confidence and identify issues before real disasters occur.
Chaos engineering takes testing further by intentionally introducing failures into production systems to validate resilience. This approach, popularized by major technology companies, helps identify weaknesses that traditional testing might miss. Controlled chaos reveals how systems actually behave under stress rather than how we assume they will behave.
Post-incident reviews analyze every outage or degradation event, regardless of cause or duration. These reviews identify root causes, contributing factors, and opportunities for improvement. Blameless culture encourages honest discussion that leads to better systems rather than finger-pointing that discourages transparency.
The Role of Managed Web Infrastructure
Implementing and maintaining active active geo redundancy hosting with multi data center automatic failover requires specialized expertise that many organizations lack internally. Building these capabilities from scratch demands significant time, capital investment, and ongoing operational overhead.
Managed web infrastructure providers bring established expertise, proven architectures, and economies of scale that individual organizations cannot match. These providers have already solved the complex challenges of distributed systems, database replication, automated failover, and 24/7 monitoring.
The financial model shifts from capital expenditure to operational expenditure. Rather than purchasing hardware, building data centers, and hiring specialized staff, organizations pay predictable monthly fees for services that scale with their needs. This approach reduces risk, accelerates time to market, and allows internal teams to focus on core business activities.
Service level agreements with managed providers create accountability and align incentives. When providers commit to 99.99 uptime enterprise hosting targets with financial penalties for failures, they have strong motivation to maintain excellent performance. These agreements provide business protection and clear expectations.
Managed web infrastructure does not mean losing control. Quality providers offer transparency through monitoring dashboards, detailed reporting, and collaborative relationships. Organizations maintain visibility into performance while benefiting from expert management and support.
Technical Considerations for Implementation
Successful deployment of multi data center automatic failover requires careful attention to numerous technical details. DNS configuration plays a critical role in how traffic routes to different regions. Time-to-live settings must balance responsiveness against DNS server load. Geographic DNS services can route users to the nearest data center based on their location.
Database replication strategies vary based on application requirements. Synchronous replication guarantees consistency but introduces latency that may impact performance. Asynchronous replication reduces latency but creates brief windows where data might differ between regions. Conflict resolution mechanisms handle scenarios where simultaneous updates occur in different locations.
Session management across regions requires careful design. Sticky sessions that bind users to specific servers can complicate failover. Centralized session stores provide consistency but create potential bottlenecks. Distributed caching solutions offer middle-ground approaches that balance performance and reliability.
Content delivery networks complement geo-redundant architectures by caching static assets close to users worldwide. CDNs reduce load on origin servers while improving response times. Integration between CDNs and origin infrastructure must account for cache invalidation during deployments and updates.
Security considerations multiply in distributed architectures. Encryption in transit protects data moving between regions. Certificate management across multiple data centers requires coordination. Firewall rules and access controls must remain consistent while accounting for different network topologies in each location.
Cost-Benefit Analysis
Investing in active active geo redundancy hosting and multi data center automatic failover requires significant resources. Organizations must weigh these costs against the financial impact of downtime and the competitive advantages of superior reliability.
Infrastructure costs include multiple data center locations, redundant networking, additional compute and storage capacity, and sophisticated load balancing. These expenses typically run 2-3 times higher than single-location deployments, though managed web infrastructure providers can reduce this multiplier through shared resources.
Operational costs encompass specialized staff, monitoring tools, testing programs, and ongoing maintenance. Organizations building these capabilities internally face higher costs than those leveraging managed services that spread expertise across multiple clients.
The break-even calculation depends on downtime costs specific to your business. E-commerce operations with high transaction volumes may justify geo-redundant architecture after preventing just a few hours of downtime per year. Content sites with advertising revenue might require different thresholds. Subscription services must consider churn rates and customer lifetime value impacts.
Competitive positioning provides less tangible but equally important benefits. Industries where reliability differentiates market leaders from followers make availability a strategic asset. Customer trust, brand reputation, and market perception all improve with demonstrated reliability.
Regulatory and Compliance Factors
Many industries face regulatory requirements around availability, data protection, and disaster recovery. Financial services, healthcare, and government contractors often must demonstrate specific recovery capabilities and maintain audit trails.
A comprehensive website disaster recovery strategy addresses these compliance needs while delivering business benefits. Documentation of architectures, procedures, and testing results satisfies auditor requirements. Geographic data distribution can support data sovereignty requirements by keeping certain information within specific regions.
Compliance frameworks like SOC 2, ISO 27001, and PCI DSS include availability and disaster recovery components. Achieving certification requires demonstrating appropriate controls and regular testing. Organizations with mature disaster recovery capabilities find compliance audits less burdensome because required evidence already exists.
Future-Proofing Your Infrastructure
Technology evolution continues accelerating, bringing new capabilities and changing best practices. A forward-looking website disaster recovery strategy must accommodate growth and adapt to emerging technologies.
Cloud platforms have made geo-redundant architectures more accessible through managed services that abstract infrastructure complexity. Multi-cloud and hybrid approaches provide additional resilience by avoiding dependence on any single provider. These strategies introduce new complexity but offer protection against provider-specific outages.
Edge computing pushes processing closer to users, potentially creating hundreds or thousands of micro data centers rather than a handful of large regions. This distribution can improve performance while introducing new challenges for consistency and management.
Artificial intelligence and machine learning enable smarter failover decisions based on pattern recognition and predictive analytics. These technologies can anticipate problems before they fully materialize, triggering proactive responses that prevent user impact.
Selecting the Right Partner
Organizations choosing managed web infrastructure providers should evaluate several critical factors. Technical capabilities matter, but operational excellence, cultural fit, and long-term viability equally influence success.
Track record provides evidence of actual performance rather than marketing claims. Request case studies, reference customers, and historical uptime data. Understand how providers handled past incidents and what they learned from problems.
Transparency in operations builds trust and enables collaboration. Providers should offer clear visibility into infrastructure state, performance metrics, and incident details. Opaque operations create uncertainty and prevent organizations from making informed decisions.
Support quality determines how quickly issues get resolved. Evaluate response times, escalation procedures, and technical expertise of support staff. Test support during the evaluation process to experience actual service quality rather than relying on promises.
Scalability ensures your infrastructure can grow with your business. Understand capacity limits, expansion processes, and pricing models for increased usage. Avoid providers where growth requires painful migrations or creates unexpected costs.
Building Internal Capabilities
Even organizations using managed web infrastructure benefit from internal expertise in disaster recovery principles and practices. Teams should understand architectural concepts, failover mechanisms, and recovery procedures.
Training programs build knowledge across operations, development, and business teams. Cross-functional understanding improves collaboration and decision-making during both normal operations and incident response.
Internal documentation captures organization-specific configurations, customizations, and procedures. While providers manage infrastructure, you own the applications and business logic that run on that infrastructure. Document these elements thoroughly.
Participation in testing and incident response keeps internal teams engaged and capable. Regular involvement prevents knowledge decay and builds confidence that your team can handle various scenarios.
Measuring Success
Establishing clear metrics allows you to evaluate whether your website disaster recovery strategy delivers expected value. Uptime percentage provides the most obvious measure, but additional metrics offer deeper insights.
Mean time to detect measures how quickly monitoring identifies problems. Faster detection enables faster response, reducing total impact. Improvements in detection capabilities directly improve overall availability.
Mean time to recovery tracks how long problems persist after detection. This metric reflects both automated failover effectiveness and manual response capabilities. Trends over time show whether your processes are improving.
Recovery point objective compliance measures data loss during incidents. Even with excellent uptime, data loss can create serious business problems. Tracking actual recovery points against targets ensures data protection remains effective.
Customer impact metrics connect technical performance to business outcomes. Measuring affected users, lost transactions, or support ticket volume during incidents quantifies real-world impact beyond abstract uptime percentages.
Conclusion
The path to true high availability requires commitment, expertise, and appropriate investment. Active active geo redundancy hosting with multi data center automatic failover represents the proven approach for organizations where downtime directly impacts revenue and reputation.
Building a comprehensive website disaster recovery strategy demands attention to technology, processes, and people. Success requires not just implementing the right infrastructure but also creating operational excellence through documentation, testing, and continuous improvement.
For many organizations, managed web infrastructure provides the most practical path to 99.99 uptime enterprise hosting. Leveraging specialized providers allows you to benefit from proven architectures and expert operations while focusing internal resources on core business activities.
The question is not whether to invest in disaster recovery but how to implement it most effectively for your specific situation. Every day without proper protection represents unnecessary risk to your business. The time to act is now, before the next incident turns potential disaster into actual loss.
Frequently Asked Questions
What is the difference between active-active and active-passive geo-redundancy?
Active-active configurations run production traffic across all data centers simultaneously, providing immediate failover and better resource utilization. Active-passive setups keep backup systems idle until the primary fails, resulting in longer recovery times and wasted capacity. Active-active delivers superior performance and reliability but requires more sophisticated data synchronization.
How quickly can multi data center automatic failover redirect traffic during an outage?
Modern failover systems typically redirect traffic within 30 seconds or less, often in under 10 seconds for network-level failures. DNS-based failover may take slightly longer due to caching, while load balancer-based failover can occur almost instantly. The exact speed depends on your specific architecture, monitoring sensitivity, and failover triggers.
What does 99.99% uptime actually mean for my business?
99.99% uptime allows for approximately 52 minutes of downtime per year, or about 4.3 minutes per month. This target requires eliminating single points of failure across your entire infrastructure stack. Most businesses cannot achieve this level without geographic redundancy and automated failover capabilities.
How much does implementing active active geo redundancy hosting cost compared to single data center hosting?
Geo-redundant architectures typically cost 2-3 times more than single-location setups when built internally, though managed web infrastructure providers often reduce this premium through shared resources and economies of scale. The investment becomes cost-effective when the value of prevented downtime exceeds the additional infrastructure expense, which occurs quickly for revenue-critical operations.
Do I need technical expertise in-house to maintain a website disaster recovery strategy?
While some internal knowledge helps, managed web infrastructure providers handle most technical complexity. Your team should understand basic concepts and your specific applications, but the provider manages infrastructure, monitoring, and failover automation. This arrangement allows you to benefit from enterprise-grade disaster recovery without building deep specialized expertise internally.
How Elevated Marketing can help
We do this work every day for businesses in Indianapolis, the DC & Virginia metro, and nationwide.
→ Website Security & Monitoring→ SEO & GEO Services→ Managed Web Hosting→ More on UncategorizedGet a free audit